
Genmo is an unusual starting point for text-to-video experiments. Its public identity is tied to Mochi 1, an open video generation model, as well as a hosted playground. That makes it useful for people who want to study an open model, run local tests, or inspect how prompt adherence changes across short generations.
It is not the best fit for every experiment. You may need more polished hosted output, stronger reference controls, native audio, more model choices, or a faster way to compare providers without managing a GPU. The best Genmo alternative depends on which of those constraints is slowing the experiment down.
Quick answer
| Alternative | Best fit | What changes from Genmo | Main tradeoff |
|---|---|---|---|
| Runway | Prompt-led cinematic shots | Hosted shot iteration with model-specific credits | No open-weight local runtime |
| Kling 3 | Reference-rich tests | Text, image, element, storyboard, motion, and audio options | Version and credit rules vary |
| Luma Ray3 | Controlled visual iteration | Keyframes, character references, video-to-video, and Draft Mode | More reference preparation |
| Pika | Fast effect variations | An effect-led idea-to-video surface | Weaker fit for open-model benchmarks |
| Veo 3.1 | Video experiments with sound | Native audio and reference-image inputs | Access and cost depend on the entry point |
| Seavid | Comparing model paths | Text, storyboard, image, and reference routes in one layer | Not a local Mochi runtime or editor |
What you are replacing when you leave Genmo
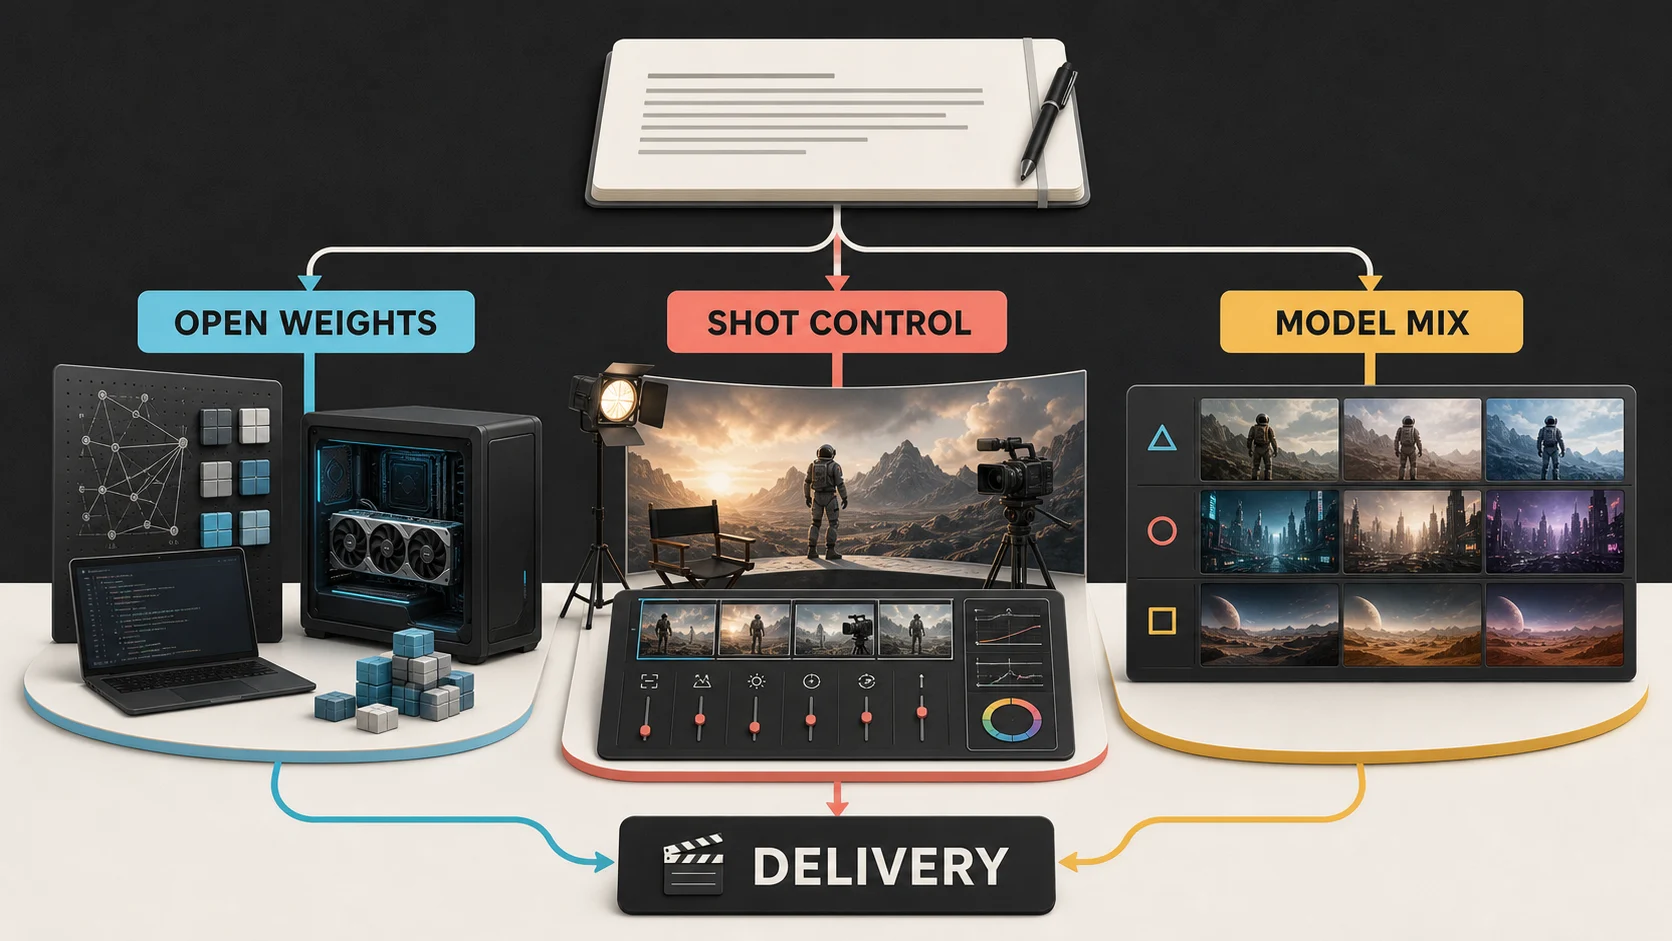
The first question is what role Genmo plays in your test. If Mochi is valuable because it offers open weights, local reproducibility, Apache 2.0 licensing, and direct model access, a hosted service is not a like-for-like replacement. If you use the playground, the migration target may instead be stronger references, longer iteration, audio, resolution, or provider choice.
The public Mochi 1 release is a short-form, 480p-focused baseline that the repository describes as a research preview with strong motion and prompt adherence. That creates four common migration motives:
- Hosted access: GPU memory, setup time, and queue management are slowing each test.
- More controls: References, keyframes, subject consistency, or motion direction matter more than prompt quality alone.
- Richer output: Resolution, sound, dialogue, or export reliability determines whether a test can ship.
- Model comparison: One model cannot tell you whether a failure comes from the prompt or the generation path.
How to compare Genmo alternatives
A fair test keeps the brief fixed while changing the generation path. Include the subject, action, camera, setting, lighting, and output intent, then record what you can control before and after generation.
| Dimension | Question to ask | Why it matters |
|---|---|---|
| Input control | Can you add a reference, keyframe, or shot plan? | Separates prompt skill from visual consistency. |
| Motion | Can you direct pace, camera, and interaction? | Motion failures matter more than weak stills. |
| Iteration | Can you revise one variable or rerun everything? | Fast retries lower learning cost. |
| Cost | Are credits charged by seconds, model, resolution, or effect? | The first render is not the keeper budget. |
| Delivery | Can you export the needed format, audio, and rights package? | A preview is not always a usable asset. |
1. Runway: best for prompt-led shot iteration
Runway fits experiments that turn a detailed prompt into a polished shot and refine it through several passes. It is a good match for visual development, product scenes, cinematic transitions, and short concepts where subject, camera, and atmosphere must work together.
Its current pricing surface charges credits by model and duration, listing Gen-4.5 at 12 credits per second. Track every revision because a failed motion pass or resolution change can cost more than the first render. Choose Runway when hosted iteration matters more than open weights. The main delivery risk is provider and plan dependence.
2. Kling 3: best for reference-rich and multimodal tests
Kling fits tests where text alone is not enough. Its current product surface emphasizes Kling 3 and Kling 3 Omni, audio-video generation, storyboarding, element references, motion control, and native 4K output. That makes it useful when a character, object, or visual identity must survive a shot.
Move from a text brief to image or reference inputs, then choose a motion or storyboard path. This gives you more ways to diagnose failure: weak reference, broad motion instruction, or a poor model fit. Kling is strong for reference-led commercials and character tests. Record the exact model and settings because duration, resolution, audio, and credits vary by mode.
3. Luma Ray3: best for controlled visual iteration
Luma Ray3 suits creators who want a reasoning-oriented workflow instead of a one-shot prompt box. The current Ray3 family highlights character references, keyframes, video-to-video, visual annotations, Draft Mode, native 1080p generation, and an HDR path.
Use a reference to establish the character, a keyframe to anchor composition, and a draft pass to test motion before spending on final quality. This works well for product movement, camera blocking, and continuity checks. It is less useful for a simple open-model reproduction test because references and keyframes add preparation work.
4. Pika: best for fast effect-led variations
Pika works when the experiment is about speed, transformation, and visual play. Its current surface describes an idea-to-video platform and lists Pika 2.5 with Pikaframes, Pikascenes, Pikadditions, Pikaswaps, Pikatwists, and Pikaffects.
That makes Pika useful for social concepts, effect tests, and quick pitches. Change the effect, framing, or source asset and compare visible variations. Define whether 480p, 720p, or 1080p is acceptable before running the test. Pika is not the natural choice for a local open-weight benchmark or a long sequence with strict continuity.
5. Veo 3.1: best for audiovisual experiments
Veo 3.1 is the clearest choice when sound belongs in the brief. Google's current Veo surface highlights native audio, sound effects, ambience, dialogue, and reference images for a scene, character, or object. Access can vary across Google creative and developer surfaces.
Use Veo for dialogue scenes, product demonstrations with sound cues, and clips where movement and audio must align. Score visual and audio keepers separately because a strong image can still fail on voice, timing, pronunciation, or effects. Confirm export, access, and usage terms before delivery.
6. Seavid: best for comparing several model paths
Seavid fits when the real problem is provider choice. Its current generation layer exposes text-to-video with storyboard shots, plus image-to-video and reference-to-video. The model matrix includes hosted paths such as Kling 3, Veo 3.1, and Seedance 2, so one brief can be compared without rebuilding the whole flow.
Use it to compare prompt adherence, motion, references, output format, and keeper effort. The boundary is important: Seavid does not replace Mochi's open weights, local inference, fine-tuning, or a timeline editor. It is a generation layer for moving from briefs to shots and testing hosted model paths.
Choose by migration motive
Choose by the constraint that caused the search:
| Migration motive | Start with | Main tradeoff |
|---|---|---|
| Keep an open, local model | Genmo or Mochi | Hardware and setup are part of the test |
| Improve cinematic prompt iteration | Runway | Credit spend grows with revisions |
| Add references and multimodal controls | Kling 3 | Settings vary by model and mode |
| Iterate with keyframes and drafts | Luma Ray3 | Preparation slows simple tests |
| Make fast effect variations | Pika | Continuity is less predictable |
| Test video with native sound | Veo 3.1 | Audio needs its own review pass |
| Compare hosted models | Seavid | It does not provide local open weights |
A practical migration test
Use a small benchmark before moving a real project:
- Freeze one brief with the subject, action, camera, duration, ratio, and delivery format.
- Run three candidates: an open or local path, a specialist model, and a multi-model route.
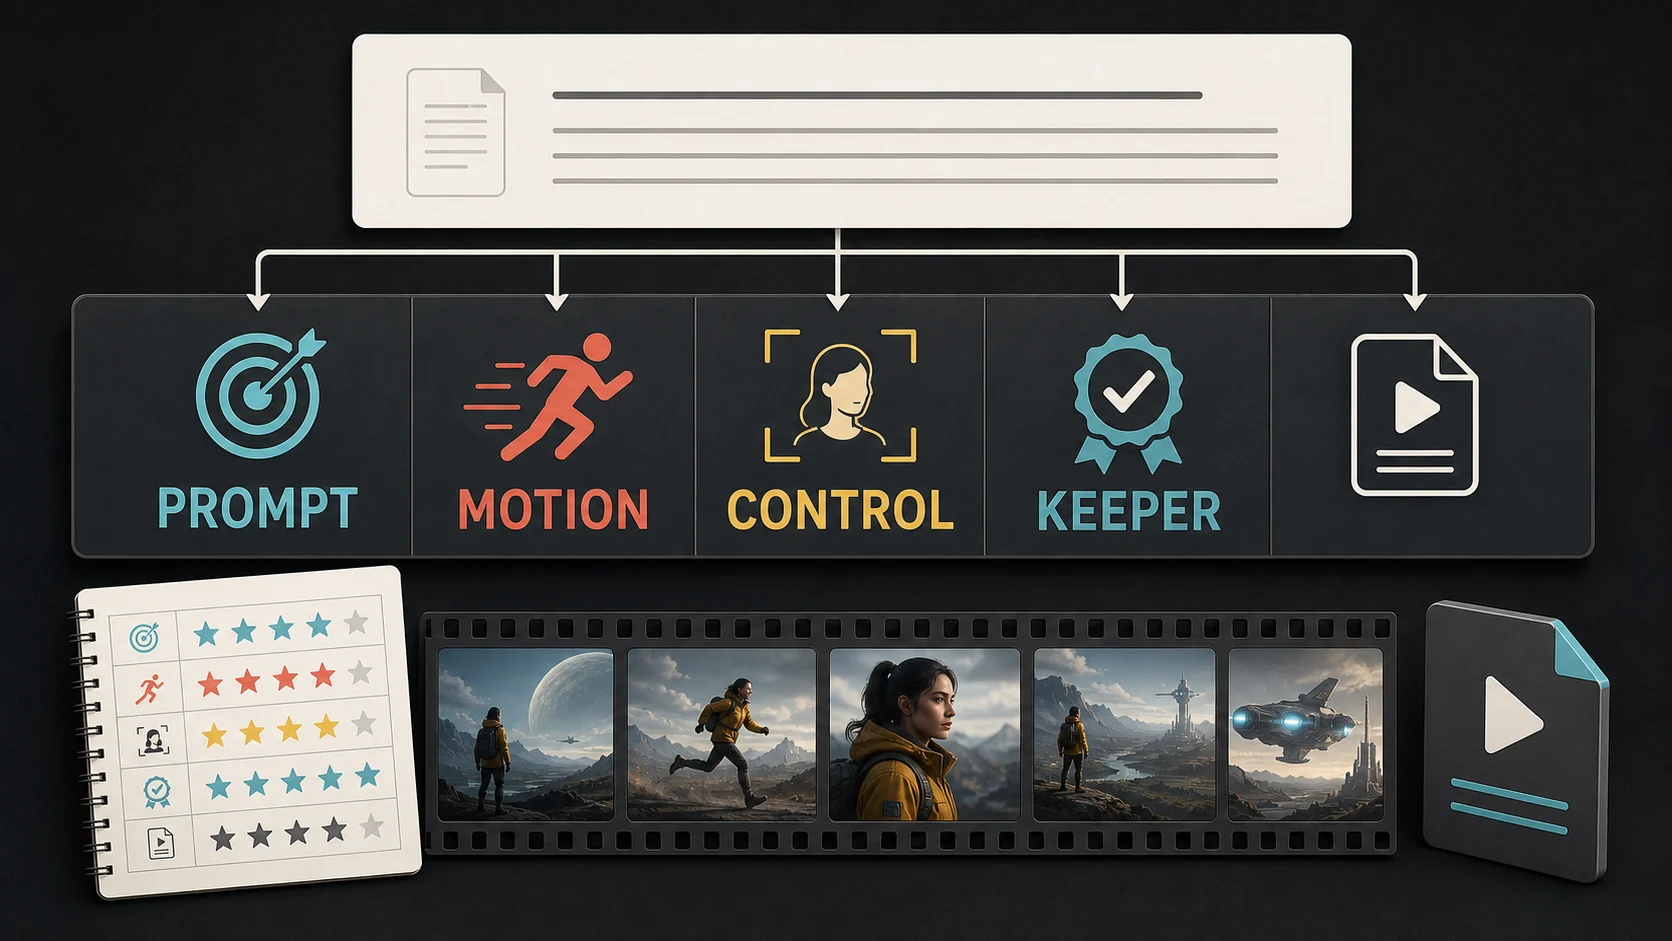
- Score prompt adherence, motion, reference consistency, useful variations, and keeper quality.
- Record credits, queue time, retries, exports, audio cleanup, and manual repair.
- Choose the lowest keeper effort, not the best first frame.
The same method works inside Seavid. Start with text-to-video, then repeat the brief through another model path. If the reference is the real variable, move the test to reference-to-video instead of changing the prompt and the input at the same time.
Delivery risks to check before switching
- Credits: Count retries, resolution changes, and failed motion passes.
- Hardware: Open weights trade provider dependence for GPU and maintenance work.
- Format: Confirm resolution, ratio, frame rate, audio tracks, and export behavior.
- References: Confirm rights for faces, products, locations, and source footage.
- Access: Region, account tier, API access, queues, and model availability can change.
- Continuity: One strong clip does not prove the next shot will match.
FAQ
What is the closest open-source Genmo alternative?
There is no one-to-one replacement when open weights and local inference are the reason you use Genmo. Mochi remains the relevant baseline. Hosted alternatives solve different problems, such as references, audio, speed, or model choice.
Which Genmo alternative is best for text-to-video experiments?
Runway fits prompt-led shots, Kling 3 reference-rich tests, Veo 3.1 audiovisual tests, and Seavid hosted model comparisons. If local reproducibility is the goal, staying with Genmo may be more correct.
Which alternatives support audio generation?
Veo 3.1 explicitly includes native audio, effects, ambience, and dialogue. Kling's current 3.0 surface also emphasizes synchronized audio-video generation. Confirm the exact model, access path, and export behavior before delivery.
Can Seavid replace Genmo?
Seavid can replace the generation workflow when you want hosted model choice, storyboard shots, image inputs, and reference routes. It cannot replace Mochi weights, local inference, or fine-tuning.
How should I compare costs?
Compare the cost of a delivered keeper, including failures, retries, queue time, resolution upgrades, audio cleanup, storage, and export work.
Final recommendation
Choose by the experiment, not a universal quality ranking. Stay with Genmo for open weights and local control. Choose Runway for cinematic prompts, Kling 3 for references, Luma Ray3 for staged refinement, Pika for effects, or Veo 3.1 when sound belongs in the brief.
Choose Seavid when hosted model comparison is the bottleneck. It tests text, image, reference, and storyboard routes without pretending to be a local Mochi runtime.